RAG Evaluation skill
Explore the open GitHub skill for examining real RAG traces, measuring the failed layer, validating the judge, and assessing production readiness.
AI Engineering Lab · Open methodology
RAG Evaluation is a method for finding which layer failed, choosing the right measurement, validating the evaluator itself, and deciding whether a system is ready for production.
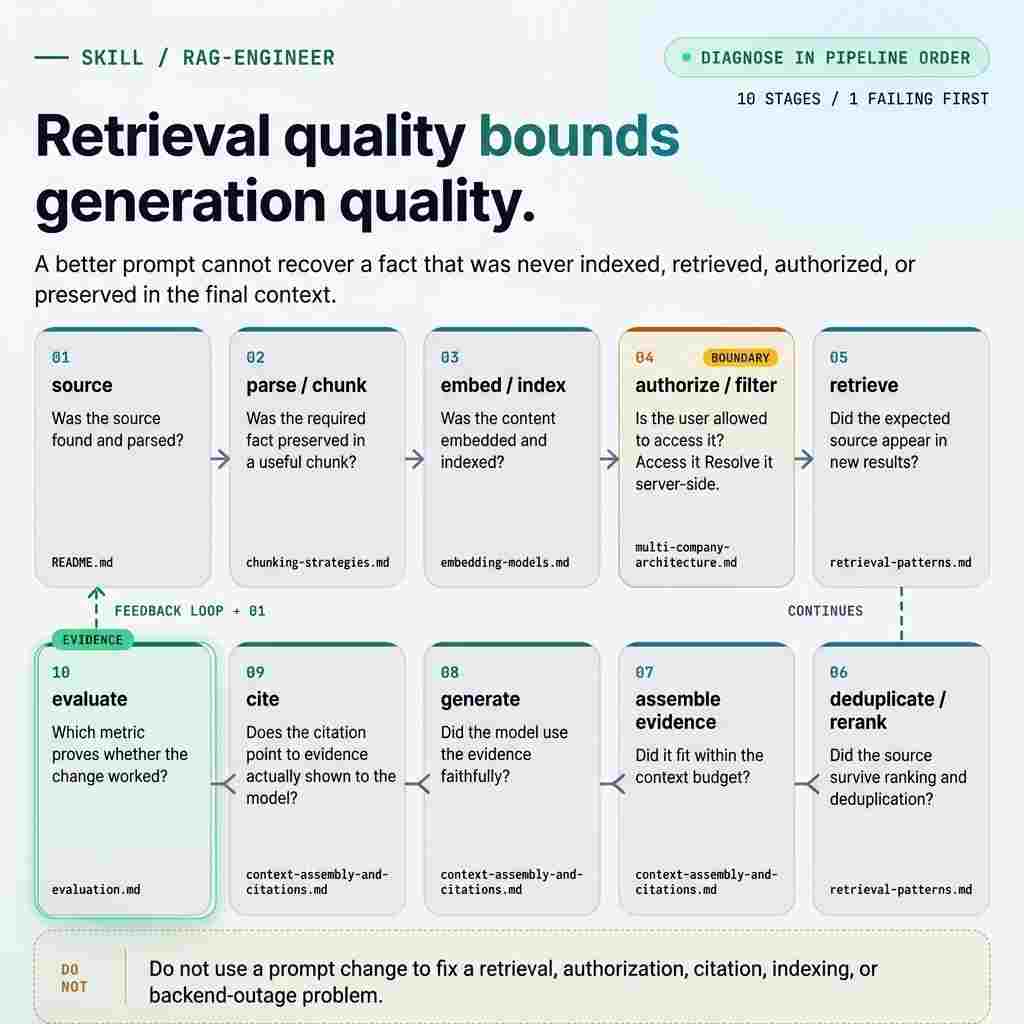
Evidence pipeline
Start with the failures users actually experience. Keep retrieval, generation, evaluation, and readiness separate so each can be measured.
Explore the open GitHub skill for examining real RAG traces, measuring the failed layer, validating the judge, and assessing production readiness.
For retrieval, use Recall@k, Precision@k, MRR, or NDCG. Evaluate faithfulness and relevance only after retrieval is sound.
Prefer code when possible and validate binary LLM judges against human labels with TPR, TNR, and a confusion matrix.
Review reliability, scalability, security, cost, data management, and core pipeline quality before shipping.
Related method
Pair RAG Evaluation with RAG Engineer to connect each observed failure to the smallest measurable engineering change.